I find it amusing that Facebook despite its high valuation and increased interest from Microsoft is still amateurish at times. One of the areas I find is in usability - there are some basic issues that any modern (or even 10 year old site) would handle better than facebook but haven't been addressed as the site grows and scales.
Here are a few examples!
Group Management
One of the areas that is really week in Facebook is group management. It seems that the whole assumption around being a group admin is that your group has about a dozen people.
For example, here is a simple but telling bug - try to remove a member in your group. About 2 months ago, this feature didn't seem to work at all. It now works, but there is no way to search for members! So in our case we have 1900+ members, and if we want to remove or block a member we have to scroll through 70 pages worth of names!
Sorting of Lists
Another example is the basic way that Facebook sorts lists. By default your friends list is sorted in alphabetical order by last name. If you do a search for Classmates, the sort order is the same - but this is not always what is needed. For example, I want to know recently updated Classmates because I've already scanned the list previously. There is no easy way to do this in Facebook.
Paging of Lists
Another basic usability issue - paging through lists doesn't actually page properly! If you click next, you'll see people who were on the previous page.
Inviting People to Groups
In groups, you can invite your friends to join. In previous "versions" of Facebook, it would only show friends in the invite list who you hadn't previously invited. Now it seems to show all your friends but if you click on the friend who has been previously been invited, it pops up a warning and doesn't allow the action. How is an improvement?
All of these are basic usability issues related to scale - what works for a friends list of 20-30 people doesn't scale as an interface if you have 2000 friends, group members, etc. But as Facebook tries to be a "platform" it needs to be able to address these concerns - these are pretty basic and most applications whether Web 2.0 or traditional client server have basic functions for sorting, searching and filtering lists!
Wednesday, October 31, 2007

Tuesday, October 16, 2007
Are AJAX enabled forms really worth the trouble?
 We have just launched our new Tribute Application for creating customized cards for donations in honour or memory of someone you love.
We used Microsoft .NET and the new AJAX library for development of our forms. Our developer teams became enthusiastic supporters of using AJAX styled controls for creating a sense of immediacy in the interface.
However, what was interesting was the new set of bugs that cropped up simply because of now using AJAX controls. Here is an example: the above form has two controls for postal code and zip code and based on which state or province is picked, we flip between them so that you can have client side validation, proper field lengths, etc. Sounds simple enough, but we went through quite a bit of work and bug fixing to make this work.
Here are a few bugs that we found in the process as examples:
1. When you click the back button the right control isn't always displayed.
2. We had styling/layout issues in Mozilla.
3. When you picked a state and then switched to province the value would disappear.
4. The switching of state was generally quite slow on some clients.
In the "old days", the interface would have been really simple - a text box submitted to a server side script. Very few presentation layer bugs because there wasn't really anything going on in the presentation.
So the question becomes - is it really worth it? For Yahoo Mail it might be, but for an average data entry form is it really that crucial?
Now that we're planning phase 2 on our project, I would be much more cautious about going gung-ho on AJAX simply because it dramatically increases the testing/bug fixing time for what amounts to a simple user interface convenience.
Friday, September 21, 2007
Software Development Metaphors
There are lots of discussions on Software Development "methodologies". They are codified sets of practices on how to do software development "correctly". When you get down to the root of each of these methodologies, the root of all of them is a metaphor. Before you adopt a methodology such as XP, Scrum, RUP, Software Factory, etc. you should really ask yourself what metaphor you believe your particular software development practices fit into and what metaphors fit your particular organization's culture. If you start there instead of at the "here is my fancy new toolbox of processes" then adoption will be higher.
So here is a list of popular metaphors used to explain the practice of creating software...
The Traditional Software Development Metaphors
Software Development as Factory
So here is a list of popular metaphors used to explain the practice of creating software...
The Traditional Software Development Metaphors
Software Development as Factory
- Heavy emphasis on frameworks (assembly line) and components (widgets)
- Use in large scale development projects (hundreds of developers) or highly distributed projects (outsourced)
- Highly centralized control of processes, tools, etc.
Software Development as Engineering
- Heavy focus on estimation techniques
- Fixes made in planning are less expensive than after “construction” has started.
- Highest project management priority is being “in control”.
- Software development as a science, e.g. objective, measurable.
- Belief that Software Development is an immature or imprecise version of engineering.
Software Development as Model/Architecture
- Architect as “GOD”
- Code is simply implementation of a model
- If the software doesn’t work, either the model is wrong or the code doesn’t implement the model properly.
- Tooling can automatically generate application from the model.
- Software models a business, a process, etc. in design. Goal of software is to accurately reflect real life processes.
- Need specialized modeling languages, expertise, and tools
Software Development as Workflow/Process
- Projects as repeatable processes.
- Workflow is defined up front, and people are compartmentalized.
- Emphasis on distribution, encapsulation and hand-off.
- Project managers are process champions – they make sure the rules are followed.
These metaphors have formed the bedrock of software development. They represent the traditional way of viewing software development as well as project management in general. They have enabled a whole toolbox of techniques, tools and templates for managing projects and software development.
The Radical Software Development Metaphors
These metaphors have become in vogue thanks to various agile methodologies, reactions against the traditional view of software and frankly a lot of failures for the traditional metaphors to come to grips with the complexities of creating software.
Software Development as Craft/Voodoo/Martial Art
- Focus on simplicity, elegance, and craftsmanship
- Toolbox approach
- Apprentice / Master / Guru model
- Software is highly dependent on people
- Software “Design” provides guide to picking solutions
Software Development as Game Playing
- Games are processes without the prescription
- Games can be open or closed, cooperative or competitive
- Rules of the game are enforced, but outcome is unknown
- Games also include collaborative activities such as sports, playing music, dance, etc.
Software Development as Book Writing/Composition/Poetry
- Iteration, drafts, reviews, etc.
- Focus on creativity within an established structure.
- Objective is known, but product is not well defined.
- Challenges in forcing creative process into rigid scope, time lines and budget are recognized.
Software Development as Learning/Experiment/Invention
- Modeling in software is about learning
- Documentation, requirements gathering is a means to collective learning
- Focus on establishment of common language
- Prototyping, experiment, measuring as a way to learn
Which one fits your culture, your organization needs, and your skill set? If you're a start-up company, then the software factory metaphor might not be the best fit. However, if you're building printer drivers with third party outsourcers in India, then perhaps it is the right model.
If you start with basic metaphors, the toolbox and methodologies such as RUP, XP, Scrum, Waterfall, etc. start to make more sense - they're expressions of the underlying metaphor. In addition, if you want to evangelize a new software development methodology (for example, those who are trying to evangelize the use of XP in a traditional RUP organization) starting with a discussion around metaphors and basic understanding of software development might help the discussion, especially with non-technical users.
One last suggestion - this discussion is a great interview topic for Project Managers. If you want to hire an "Agile" PM, then start the interview with the list of metaphors and ask them which one they believe fits their style of working. If they pick one metaphor, then get them to explain how their PM toolbox (GANTT charts, risk matrices, status reports, etc.) fit into the metaphor. The traditional toolbox can be used in an agile context if the underlying metaphor is right - there are ways to use MS Project even if you believe that Software Development is more like writing a book then building a bridge.
Monday, August 27, 2007
The DigiBarn and Facebook - A Killer Way to Meet Old School Geeks?
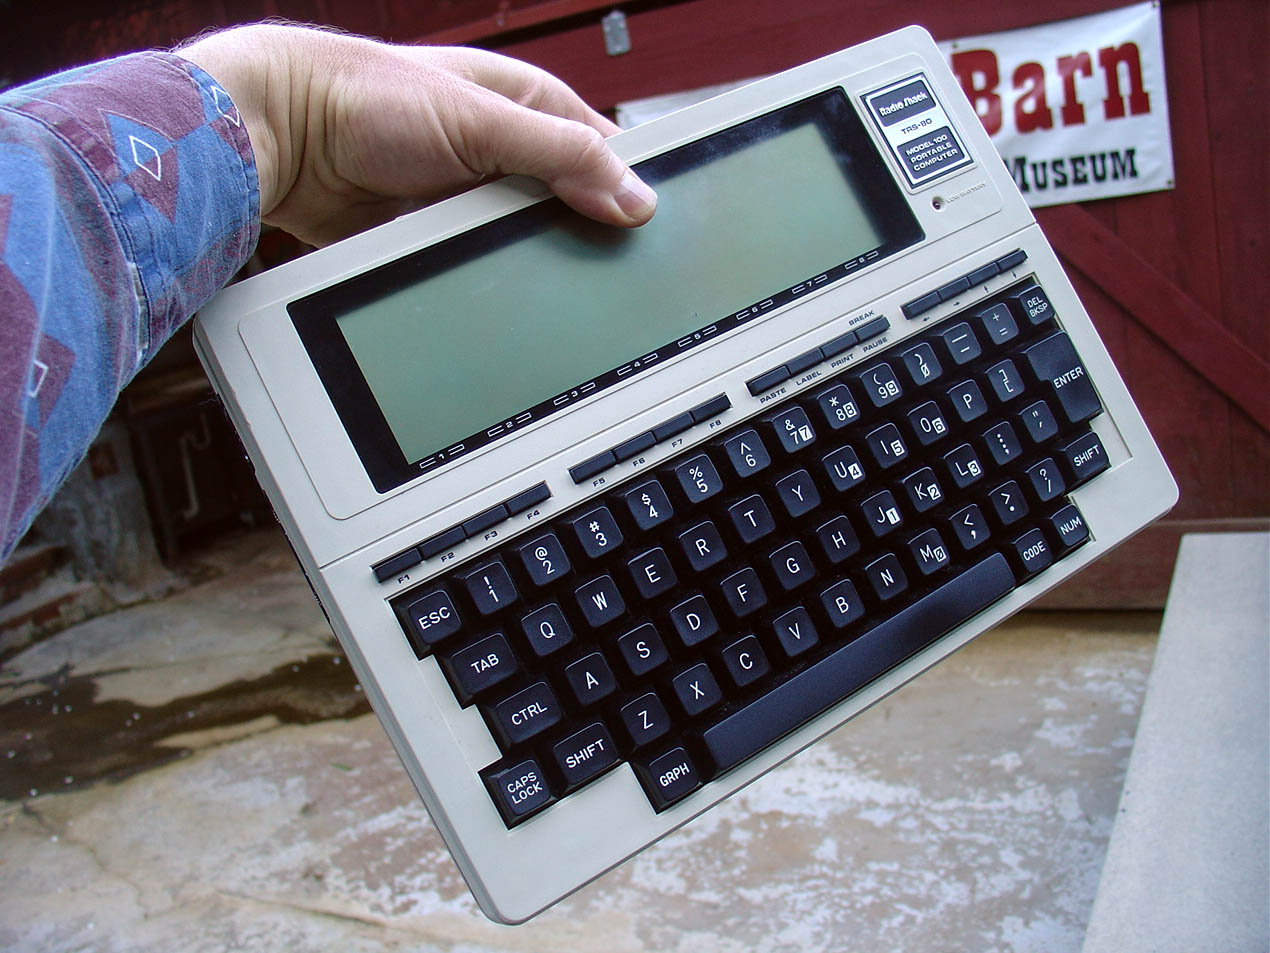 The Digibarn is a museum of old computers. They have a great virtual collection of every computer that I've ever owned and then some.
Here is just a small sample of weird computer systems I've owned or used extensively over the years:
Facebook currently has lots of curious personality matching tests such as "Which Disney Princess Are You?", Celebrity matching applications and personality comparison tests.
So here is a killer app idea for meeting old school geeks - why not combine the power of the Digibarn with the social network for Facebook to create a profile based on computers you owned over the past 20 years? Imagine having a date with someone who also owned a TI 99/4A, just like you? Imagine the nostalgic conversations about GOSUB, sprites and tape drives you could have over dinner?
At least it would be better than that Zombie Facebook application floating around these days...
Thursday, August 23, 2007
Take that First Step Toward Becoming a Legend (in IT Governance)!
I received this spam from Oracle the other day and I nearly fell off my chair laughing about how marketing people can really get things wrong if they try to apply consumeristic jingoisms to IT related products:

Do people in "IT Governance" (whatever that is supposed to mean these days) really need such a confidence boost that they need to be pandered to by suggestions that the systems, memos and processes they put in place will make them "legends" and their companies "Admired by your industry, as a leader in IT governance"?
And as an executive, imagine if the first impression of your company's brand was a "leader in IT governance" or that the "company's legacy" was really good IT governance?
I hope I never work for that company... :)
Tuesday, August 21, 2007
Best Logging Strategy using Microsoft Enterprise Library?
The Microsoft Enterprise Library has a really good Logging Application Block that allows you to make your logging infrastructure configurable. By simply typing in the following code:
Logger.Write("log this!");
you can log to a destination configured in your config file.
The Microsoft Enterprise Library out of the box provides the following destinations for logging messages:
Logger.Write("log this!");
you can log to a destination configured in your config file.
The Microsoft Enterprise Library out of the box provides the following destinations for logging messages:
- File
- Database
- Message Queue
- Text File
- WMI Event
- Custom location
I took our web site and our main global error handler and did a dump routine of all exceptions to the log and it worked great. But the discussion in our team arose - where should we log? Here are some of our ideas as we debated the issue:
- The least error prone seems to be the flat file. The custom location seems the worst option simply we would hope that our proprietary code is less tested in less real world scenarios than Microsoft's Enterprise Library components.
- The idea of logging to the database is attractive from a reporting perspective, but everyone on the team felt like it was risky given that the most typical scenario for an error in the application itself was a database related error. I suppose if we had the logging database seperate from our application database then this would reduce the risk, but we don't have the resources for such a move, so if our application were to kill the database it would take down any logging sources there as well.
- Even with the flat file, it is possible that it will fail. A simple scenario for it failing would that the file is read-only or the ASPNET process doesn't have permission to access the file. So we need at least two logging mechanisms to provide redundancy. The Enterprise Library allows for this - you can configure more than one listener for every log message being written.
- Our second challenge with using flat files is that they no provide a notification mechanism like email. So if there is an exception, the file has to be constantly monitored or periodically checked. Therefore, combining an email message and a flat file backing store seemed like a decent combination. If the email fails, then we may not know for a day or two but at least the error will be logged. If the file fails, then at least we'll get the email.
- The event log is not a bad option either and its generally easier to monitor as most monitoring tools already handle event log monitoring. The one issue with using the event log that I have found is that if you use an event log source that doesn't exist the logging will fail without any notification to you. Your error will simply disappear and won't be logged. You can use any existing EventLog source or create a new one in the registry for your custom logging needs. In addition, you have to make sure that the ASPNET account has permission to write to the event log.
That's where we are at so far - its not quite bullet-proof yet but its getting there. If you have any further suggestions or thoughts, leave them as a comment!
Arcade Game Prices are Finally Catching Up With Inflation
I've been playing arcade coin-op games since I was a little kid. When I started playing these games, they were 25 cents a throw. If you were good at them of course your quarter could go a long way. For example, there was a game called WonderBoy that I could play for about 45 minutes on one quarter.

Somehow despite 20 years of inflation, the price of an arcade game was stuck at 25 cents. Eventually, the prices went up by multiple credits being required, especially for newer games. The current arcade games seem to cost on average $1-2 per contest.
But if you went to the back of the arcade, you could still typically find an old Galaga, Gyruss or Pacman sitting in the back still running for a quarter a throw.
Well not so fast anymore - I was in one of the last arcades left in the city and these older games have now been replaced by emulators which allows the arcade owner to change the price and also house multiple video games in a single console. This makes sense - given the size in memory of any of these old video games, you could house hundreds of them on a single memory chip.
So I had fun today playing the old favourites, but I'm a bit disappointed that it cost me 50 cents. I guess after 20 years of dwindling attendance and increasing costs, the prices have finally gone up.
Thankfully, I have MAME which allows me to play any old video game for free!
Friday, August 17, 2007
Is Google Analytics Having Trouble Keeping Up?
Since I started this blog, I have been using Google Analytics to measure traffic to the site. In general, its a fabulous service and works really well, until recently.
I've noticed that in the past month or so, Google Analytics seems to have trouble keeping up with the traffic. I've noticed that the numbers reported are lower than expected and stay that way for 1-2 days and then as presumably the engine crawls through the right logs in queue, it catches up.
One way to tell for sure whether you're having a similar problem is compare your Google Analytics numbers to your Ad Sense numbers. Ad Sense seems to be more accurate and is updated in real time. Google Analytics is queue based and so tends to need some time to catch up. I've found in recent days that Ad Sense gives me a better indication of short term stats than Analytics.
For my blog, this is not a huge problem. But this is yet again a mark against the "software as a service" model - would you want to trust your corporate infrastructure to a queue in the cloud that can get bogged down because of an influx of unexpected growth?
Monday, August 13, 2007
Ad Words and Negative Content
The great site Worse Than Failure had a few images today of examples where legitimate ads were being shown side by side with negative content:


Having ad sense on my blog, I have noticed the same thing. I wrote a couple posts on the failure of Canada's tax software, and if you go to this post the ads displayed are for tax software!
Isn't this a pretty basic requirement for online advertising, e.g. don't put my ad for Levi's Jeans on a web page where the content is "I hate Levi's Jeans!"? Why after 10+ years of online advertising has the experts at Google and others figured out how to targets ads to the right content. In my example, the right ads would be those marketing to people reading about the failures of the tax system, e.g. tax lawyers, H&R block, etc. and not tax software providers.
Isn't this a pretty basic requirement for online advertising, e.g. don't put my ad for Levi's Jeans on a web page where the content is "I hate Levi's Jeans!"? Why after 10+ years of online advertising has the experts at Google and others figured out how to targets ads to the right content. In my example, the right ads would be those marketing to people reading about the failures of the tax system, e.g. tax lawyers, H&R block, etc. and not tax software providers.
Project Planning in an Agile Project
Tate Stuntz has an interesting post on his blog arguing that Project Plans are obsolete and hard to maintain when doing Agile projects. In my experience on agile projects, project planning and Gantt chart making definitely has to change, but there are still ways I think you can make MS Project and Gantt charts work for you in an agile context. Here are my recommendations based on my experience:
- Learn to use MS Project efficiently (see my previous post for recommendations). I've seen PM's take 2 weeks to build a project plan - if this is you then trying to work this way in a 2 week iteration cycle means you're not moving fast enough. You have to be at the point where you could re-boot your project plan in a matter of hours so that you can adjust quickly.
- Use MS Project for planning and not for tracking. If you're working with short iteration cycles, you'll see improved tracking by simply management by walking around. In addition, measuring project velocity is more valuable than percentage complete since in an Agile project the finish line is not always defined.
- Use a project plan for iteration planning at a macro-level and not for iteration tracking within an iteration cycle. What I like doing is maintaining a project plan with a simple list of user stories in each 2 week iteration. That allows me to track dependencies between user stories pretty easily. At review time at the end of an iteration, we discuss the next iteration with our stakeholders and reset expectations by re-forecasting the plan (which takes no more than an hour of work). That gives stakeholders a good understanding of what we currently see as in and out of scope and when features may be coming up. This is highly valuable and I find is critical for buy in for stakeholders - if the response from the team is simply, "we can only see to the end of the next iteration cycle" this tends to make business users very nervous.
- If you need pretty Gantt charts, one of my favourite methods is to use Visio - it provides pretty Gantt charts for presentations without the fuss of Project.
- I tend to use the whole team as a big pool for planning iterations. This gets you out of the micro-detail of having to assign one user story to one person, another user story to another person and so on. If I have 4-5 developers on a team, that gives me 70 hours x 4-5 developers for a total iteration budget of 280-350 hours. I can then do a good estimate of each user story that includes planning, development and QA with the team. We simply add up a bunch of these stories into the budget and that becomes the iteration. The way to do this in MS Project is to take your steps and instead of assigning individuals assigned to each task and running them in parallel try simply taking a generic role of "developer" and assigning them at 500% to every task in sequence. You can then tell how much time you're going to spend across the entire team without having to fuss with all the micro-dependencies.
- For preliminary planning, use low-tech Gantt chart tools such as whiteboards, post-it notes, etc. I can create a Gantt chart without MS Project using a white board, some markers and post-it notes. This works great without the overhead of the tooling getting in the way. If you want to preserve it, simply take a digital photo of it and store the picture.
I think if you follow some of these techniques as a Project Manager, you can still sleep at night without feeling completely out of control and yet move faster and leaner. In addition, you can use project planning to help sell the concept of Agile to stakeholders who aren't as comfortable with the XP style of development and give them the comfort of a traditional project plan without locking yourself into the traditional bureaucratic approach to Project Management.
Good CIO Level article on Silverlight
CIO Magazine posted a good summary on Silverlight. We used the technology in a Proof of Concept to build a kiosk for our donor hall and from a user experience perspective it's a great toolset. CIO is right to point that Version 1.1 is the version you want if you want to target the platform as it supports the .NET framework and includes support for LINQ and web services.
Compared to Flash, the biggest advantage I see is that XAML is true 3D. I remember building things like car configurators for BMW and to try and get Flash to do fake 3D was a huge challenge. Silverlight is real 3D which means that doing animations that include zooming, tiling, sliding, and using 3D models could lead to some very interesting interfaces.
I'm interested to see how this platform evolves - I can see this tool becoming a real hit in the business applications space. Think of all the VB.NET intermediate developers out there who struggle with creating a really nice interface to an otherwise functional application. With a little bit of creative design and some nice tooling, Silverlight could turn a boring non-user friendly database application into something much more intuitive.
Friday, August 10, 2007
Low Tech Approaches to Requirements - Part 3
For those who missed Parts 1 and 2, see the following previous posts:

- Part 1: Different Techniques on using non-tech tools for requirements gathering
- Part 2: Using existing tech tools in simpler ways to speed up requirements gathering.
One of my staff sent me this image today and I thought it was a great example of how to use low-tech approaches to conversations. He simply took a screen shot of a screen, threw it into MS Paint and then started making changes with the developer beside him.
Between them in 5-10 minutes they had a "language" for what the marks on the screen mean:
- Red lines through something mean to get rid of it
- A box with text means to insert a new column
- A line on a checkbox means that on checking it something will happen
- etc.
So instead of using UML, fancy wireframes, or some bureacractic documentation process, try simply taking a screen capture and throwing it into Paint!
Wednesday, August 8, 2007
Managing Configuration Files and .NET
I've been using the .NET config files lately, and its been rather frustrating lately because of the confusion that arises when running a bunch of different ways to access the same code.
In my scenario, I have a class library called DBAccess.dll and I call it in the following ways:
1. From a web site using the ASP.NET built in web server launched from VS 2005.
2. From a web site running in IIS.
3. From a forms application
4. By running TestDriven.NET using a seperate test assembly.
5. From a windows service.
In all these cases, I'm expecting to get configuration values through the main configuration file for connection string so that it can be used by Microsoft Enterprise Library.
With so many options, .NET doesn't make it easy for you because of the differences in naming conventions on the default configuration file, e.g. in the case of a web app it expects a web.config, a forms app expects an app.config and if you run the NUnit application it wants the assembly config file, e.g. DBAccess.dll.config. Maintaining all these configuration files is a nightmare!
So in sorting through this, I came up with a few basic strategies to combat this configuration file overload:
- If you add an App.Config file to your class library project, it will automatically translate this into Assembly.Dll.Config for you.
- For NUnit, it expects a config file that is rooted to your test assembly. It does not read any dependent assemblies config files, app.config, web.config, etc. even if its the same directory of your assembly. Alternatively, you can add configuration information directly into the app.config file of the NUnit executable (either the GUI or the Console) but this isn't a very portable approach.
- If you have an App.Config file and an assembly config file, .NET will always read the App.Config file. It does not by design read your assembly specific config files. There is some code floating around that can do this for you if you want to have more distributed configuration mechanisms that are attached to assemblies instead of executables. This is one way to mitigate the problem of re-using an assembly across multiple projects where some are web projects and some are forms projects.
- Another great alternative is to use proper build files instead of the default studio builds. Either MSBuild or NANT will allow you the flexibility to store a single configuration file and rename it and then deploy it to the appropriate destination. The tricky part would be that you may need a configuration file named Assembly.Dll.config for your unit tests if you've incorporated them into your build process and a final App.config or Web.config for running the executable.
- Another great idea that I have used before is to use the Microsoft Enterprise Library to specifiy an external configuration file. This removes the naming problem with your configuration files in that you can have a seperate external file that represents the master configuration file and simply have Web.Config, App.Config, Assembly.Dll.Config point to your external file. This works quite nicely in my experience as long as you remember to add the external file to your project and to configure studio to always copy it into your build directory.
- You can build your own configuration loader. I have done this with custom defined configuration sections by having code in the custom section that contains a path to an external configuration file. You can arbitrarily load up any configuration file in code and grab whatever sections out of it. This is really useful for custom configuration sections where you want to provide code that saves and loads the configuration file with an arbitrary name. One important note with this strategy - there are cases where the Enterprise Library does the configuration loading for you, e.g. the DatabaseFactory will load connection strings for you automatically. In these cases, you cannot provide a configuration section or source as an object so you're stuck with the App.Config, Web.Config, etc. as a starting point.
- The ConfigurationManager in .NET allows you to open the Machine.config file. You might want to peer into this file directory to look at global values instead of your local App.config values.
- You can use a complete different configuration framework - no is forcing you to use App.config just because it's there (although most people do so). For example, look at Nini as an option (although I haven't tried it yet!)
I hope that provides some ideas on how to manage configuration files in a way that will allow you to have more re-usable configuration schemes than a basic App.config or Web.config file so that it can be used across multiple projects and different application contexts.
Tuesday, July 24, 2007
Test Driven Development When Writing New Code
I have been doing TDD for several years now, and I can still not get around the recommendation to test first to the point where it breaks the code, write enough code to pass the test, and then go to the next test. In my experience this tends to work with mature code bases where there is a chunk of existing code that is being changed. However, I'm not sure this approach works for new applications that are being built from scratch. In my experience, a less purist approach seems to work for me:
For code changes in a larger mature application, I like the traditional TDD process of making new tests so that they fail, writing code to fix the tests and then regression. But for coding applications from scratch or starting a new major code project, I find a looser style tends to produce better results.
So with any agile technique, don't get to ideological about the approach - in my experience, TDD is best used as an approach and not a rigid perscription.
- Write enough code to get something at least working minimally. If you think of a use case, I'm not sure there is much point in writing gobs of test cases before you even have a primary path through the use case. The XP methodology talks about an architectural or design spike, but in my experience there is also a coding spike. For example, it might be the first iteration that instead of writing code + tests we just write as much code as we can to push through the primary path as widely as possible instead of trying to be exhaustive in our testing.
- I use at least a basic unit test in NUnit as an entry point in all code debugging. That enforces the practice of having tests but also provides a useful way to gain entry into the code without web pages, windows forms, or a global main method. Using TestDriven.NET, you can simply right-click a test and run it right in studio using the debugger, NUnit, NCover, etc. and I find this higly efficient when writing new code.
- There does seem to be a drop off point where writing more and more tests provides less value, as in any testing effort. I'm seen some overly puritanical approaches to TDD where it was insisted that every boundary condition was to be coded up as a unit test no matter how unlikely the scenario or risk. In my experience there is a point where coding these scenarios is not worth the benefit of the test. In addition, I have found that in some cases it is still easier and better to manually test something than to try and code it up as a test.
- I definately like the idea of using build scripts and NUnit tests when making modifications to code. However, In my experience the tests actually don't change as much as the underlying code. In some cases there are new requirements but in many cases they are implementation changes. As long as the existing tests are still green after the change, then no new tests are required.
- There seems to be a trade-off between quick progress and the feeling of "being on a roll" and the pace of TDD which tends to be plodding but regular. Again, I think a less purist approach is best - at some points you feel your creative juices flowing and you want to plow through 2-3 pages of code in one go without writing exhaustive unit tests for each little method. Other times if you're being more cautious you want to test the living hell out of every line of code. As a mature developer, you have to feel the right pattern depending on the code you're writing.
- Lastly, I think its critical that at a minimum unit tests are written before code is checked into source control. That way if you have continuous integration the unit tests will run on every build. It seems also just a courtesy - you might have insight on why you left out some tests but your team mates might not. So before checking in code make sure there are tests to go with it. I find also that the unit tests are really a good description in code of the requirements so for new code its really helpful to have them as a guide.
For code changes in a larger mature application, I like the traditional TDD process of making new tests so that they fail, writing code to fix the tests and then regression. But for coding applications from scratch or starting a new major code project, I find a looser style tends to produce better results.
So with any agile technique, don't get to ideological about the approach - in my experience, TDD is best used as an approach and not a rigid perscription.
Example of Fat Code
Why exactly does the Google Toolbar need to be 47 megabytes?! It's a tool bar for heaven's sake...
Monday, July 23, 2007
Agile Tools for .NET Part 2
This is a follow up to my previous post on Agile Tools for .NET. I got to the office and I noticed a few more tools that I missed in my previous post.
Confluence
Atlassian's professional WIKI solution, it works great with JIRA and provides a really nice WIKI solution. For those who want to travel light with documentation, WIKI's provide a nice fit for technical documentation, build documentation, internal designs, etc. as they easily accomodate rapid changes, are completely web based and allow for automatic version tracking.
Data Dictionary Creator
One of the principles of Agile is make your code self-documenting. What about making your database self-documenting? You can do this in SQL 2005 in T-SQL by adding meta-data and descriptions to each field in your database. The Data Dictionary Creator tool does the same thing through a nice GUI and allows for export and import of the documentation. You can then document your database and store the meta-data in source safe for version control and safe keeping. In addition, you can export the descriptions to an excel file for instant documentation!
Wisdom Screen Hunter
Not really a development tool, but how many times have you been creating documents and wanted a quick screen capture? Forget using the PrntScrn and fiddling in paint - use this tool. Its free and allows you to capture any arbitrary rectangular area as well as any active window. Simply hit F6 and off you go.
Sunday, July 22, 2007
Agile Tools for .NET
The following is a list of tools for doing agile based development with Microsoft .NET. There are quite a few tools out there that will accelerate your use of continuous integration, test driven development, source control integration, etc.
I have used all these tools - most I use on a daily basis. They are highly recommend and most are either low cost or free.
JIRA
Best tool for task management. For more details see my review of JIRA from a previous post. It's bugzilla on steroids and is much better and simpler than most windows based tools. It's java based, but there is still no reason not to use it for .NET based development.
NUNIT
NUnit is an implementation of the XUNIT framework for .NET. It allows you to create unit test classes that can be run by either a GUI or console application. NUnit will also integrate into your build process so that on each build, you run through your automated tests to make sure they still pass.
NANT
NANT is a port of the ANT build tool from Java. NANT allows for build scripts based on simple XML files. NANT can do things such as compile code, deploy assemblies, manage directories, start and stop processes, run executables, etc.
NCover
NCover is a code coverage tool for .NET. It will instrument your assemblies when they are built to analyze each line of code in your assembly and whether it was actually executed (exercised). If you combine this with NUnit, you can then tell how much your unit tests actually go through every path of code.
dotTrace or Ants Profiler
Either tool will do, but personally I like Ants Profiler better and you can get it as a bundle with Ants Loader for cheaper. Both tools do the same thing - they profile either memory or performance data for your executing code. You can profile an ASP.NET web site, a Winform application or a Windows Service. What you will get in the case of memory profiling is the ability to snapshot at any point of execution a picture of what is in memory. This can help with objects not getting garbage collected properly or where you're running into memory issues. For performance profiling, the tool will tell you the amount of time each line of code took to execute. This can be useful for performance testing in that you can see the breakdown of time for a method to isolate the particular lines of code that are taking the longest.
Cruise Control .NET
Cruise Control is a port of the java application of the same name. It is a continuous integration server which will fire a build on every check into your source code repository. It can run either a NANT script or an MSBuild script or simply tell Visual Studio 2005 to do a build. It then stores the status of each build in a little intranet site that you can monitor and it can email you notifications as well. This provides an automated way to integrate code and test to make sure it builds and passes all your unit tests.
My Generation
My Generation is a code generator. It ships with a number of templates for generating O/R mapping code for frameworks such as Gentle, NHibernate, DAAB, etc.
TestDriven .NET
This is one of my favourite tools. It allows you to integrate your unit testing right into studio. Want to run one of your NUnit Tests? Just right click on the test code and up comes a Run with option that you can then run with the debugger, NCover, NUnit, etc. The one I use most is run with Debugger as it means you can step through the code hit by each of your unit tests.
ANKH
Ankh is a subversion add-in for Visual Studio 2005. For those who are using subversion as your source code control system (and I would recommend subversion in general over Visual Source Safe) it allows you to update and commit code from the solution explorer window. My only problem with this tool is that its quite slow especially if you have large projects, so you may find it easier to check in with external tools after a while. But for those who are just getting used to subversion, its a great first step.
Thursday, July 19, 2007
Getting to the Finish Line in an Agile Project

One of the great potentials of Agile software development is flexibility in changing requirements. We currently use agile methodologies and have scheduled 2 week iterations. We have show and tells with stakeholders every two weeks where we show them where things are at and gather new user stories, functionality changes and other feedback to plan for the next iteration.
One of the challenges we have found with this approach is that the project quickly turns into perpetual development. One of the advantages of a traditional waterfall model is a solid arc in development and a very specific deliverable - you have a good definition of when you're done. In an environment where the requirements evolve, the time lines are fluid and the stakeholders are not that experienced at software projects we are finding that this means that the project never seems to end! Every two week iteration, stakeholders simply pile on new requirements and the launch date drifts away.
In a consulting environment, this isn't such a bad thing if you're on a time and materials engagement - the client simply gets to spend their money as long as they want. But in an internal development team, this poses a challenge because most stakeholders aren't really aware of how much money they are spending and they simply keep monopolizing the team. In the meantime, there are other projects or priorities queueing up in the background.
Based on what we have found works, here are some practical recommendations on how to combat this problem:
- Establish clear business objectives and as many solid functional requirements as possible. There is a happy medium between XP style iterative programming and a rigid waterfall model. Try to put some acceptance criteria that can be measured so that the entire team has a common understanding of the target.
- Remember the law of triple constraints - of cost, resources, and time changing any of these impacts the others. Make sure that stakeholders are aware of the real cost (even if it is an internal cost) through an internal budgeting model. In our organization, we have a shared cost model in IT but we can allocated the shared cost to any department we choose. In cases where we see departments monopolizing our time we can allocate more cost to them. This gives internal stakeholders an incentive to prioritize and conserve resources.
- Make stakeholders compete with each other. This is pure politics but it works. The easiest way to stop a project is to simply tell another stakeholder that they're waiting in the queue behind someone else. There will be a pretty quick meeting between stakeholders where one will start to put a lot of pressure on the other to get their project done quickly or to get out of line altogether.
- Time box and resource constraint the project explicitly. We do this quite a bit with reporting needs which seem to continually evolve ad nauseum. When we start these types of projects, we establish a budget of 2-3 iterations and that's the budget. The requirements can evolve but there continues to be pressure on the stakeholder to get it right the first time or else lose their window.
- Always have a phased approach with Phase 2 and 3 already planned in Phase 1. This gives the stakeholder the ability to still feel they're going to get a change at some point but perhaps can live with launching without it.
- Be vigilant and communicate often about what's currently in and out of scope. I'm not sure whether stakeholders intentionally play dumb or whether people simply don't hear bad news but I've experienced several times the case where three meetings in a row we hear questions about a feature that we've already ruled out of scope and there is genuine surprise from the stakeholder that they're not getting a particular feature even if its been already discussed, documented, etc.
- Have really strong leaders in QA. QA Leads, especially in the latter stages of projects, become crucial at communicating and organizing priorities. A great QA Lead can manage stakeholders on a daily bug review meeting and can handle the constant re-negotiation of last minute feature requests, low priority bug fixes, etc. and keep the process moving towards launch. If the project loses velocity during the stage it opens the door to ever increasing scope change. If the project has high velocity then everyone on the team feels like they better prioritize because time is running out and the project is going to launch without them. This helps crystallize priorities and puts good pressure on stakeholders to commit to the minimum work required to launch.
I've been in projects where we sat at 90% for 5 months because we kept stalling as we closed in on the finish line. In addition, I've been on projects with internal teams where the stakeholders simply got used to having a software team at their disposal week after week and their was never any pressure to launch anything or to stop working.
As a project manager, your goal is to launch - 90% complete is really 0% complete especially if it's still just running in development or still buggy in test.Wednesday, July 18, 2007
Can You Trust Second Life Charity?

At the foundation, we are interested in Second Life. For those who are not familiar, Second Life is a virtual 3D world that allows for users to create custom content, communicate with others in a virtual world and buy and sell items in a virtual currency. What makes it unique is that the virtual currency can be converted into real cash, allow for the conversion between the virtual and the real.
Commercial activities have evolved over the past year or so in Second Life to include things like virtual real estate, virtual products, etc. In the past little while, charities have started doing virtual fundraising by having virtual walkathons, virtual campaigns, etc. in Second Life. The virtual currency they raise they then convert to real dollars to help real people.
So here is the basic question - how do you ensure a trusted conversion between the fantasy and the real? In the case where a Second Life user is buying a virtual good, then there is no real issue - they pay virtual money and instantly get a virtual hat, a virtual house, etc. But if you donate virtual money to a virtual charity, how do you know that its really going to the charity? This is true for commercial conversions as well, e.g. if you pay in virtual currency for a physical good, how do ensure that the vendor is legitimate?
The number one objective for a fundraiser is raising money for their respective cause. But a very close number two is ensuring the maintenance of its brand, reputation and trust with its donors. Its critically important because its the only long term asset a fundraiser has at their disposal (in the same way as Nike, Sony, or Coca Cola).
There are a couple potential ways you can verify that a charity asking for money is legitimate and sanctioned:
- Check the charities web site. For example, the American Cancer Society publicizes its Second Life Relay for Life and provides instructions on how to get involved.
- Call the charity. If the person asking for money is legitimate, they'll be registered in some way as an event organizer.
- Ask the person in Second Life basic questions like: do you have a contact I can talk to, how do I verify that you work for the charity, do you have a tax number, etc. The person should have a way to give you information that can be verified - at least that shows the person has some basic knowledge of the charity they are promoting.
If you cannot verify, I would not donate a single L$ as you have no way to ensure the money is actually going to charity.
Creative use of Delegates in .NET
I normally don't use delegates, since I don't do a lot of events programming where they are commonly used. But I was building a class library the other day and found a good use for them.
Here is the scenario: I have a series of methods that allow for merging of records in our main CRM. In order to connect to the CRM, there is a series of setup and tear down calls that have to be made such as connecting, logging in, etc.
So I found myself creating a dozen methods that all looked something like this:
public void mergeAddress(String masterID, String mergeID)
{
try
{
bunch of set up code
meat of the method
bunch of tear down code
}
catch (Exception e)
{
throw new MergeException("Unexpected error in method mergeAddress", e);
}
}
I found myself copying and pasting this chunk of code over and over again, which is always a good sign that some refactoring is required.
My solution was to use a delegate to represent the meat of the method in the middle. Therefore, instead of having a bunch of methods that repeat the same code over and over again, I can now rewrite the method to look something like this:
protected delegate void mergeDelegate(String MasterID, String MergeID);
public void mergeByDelegate(del method, String MasterID, String MergeID)
{
try
{
bunch of set up code
del.invoke();
bunch of tear down code
}
catch (Exception e)
{
throw new MergeException("Unexpected error in method mergeAddress", e);
}
}
Now the method becomes like a prototype - I can keep the set up and tear down in one place and simply sub in the method call in the middle.
(FYI, You could do the same thing by splitting the method into three chunks, moving them into a class and sub-classing the method in the middle, but I think using a simple delegate is easier.)
To implement the prototype now looks something like this:
public void mergeAddress(String MasterID, String MergeID)
{
mergeDelegate del = this.mergeAddress();
mergeByDelegate(del, MasterID, String MergeID);
}
public void mergeAddress(String MasterID, String MergeID)
{
meat of the method
}
All the set up and tear down code is now centralized into one method. The part that changes in the middle can now vary in a variety of ways.
Hope this helps everyone with another way of using delegates...I've always struggled to find a use for them.
Tuesday, July 10, 2007
Low Tech Approaches to Powerpoint Presentations
Take a look at these videos as a low tech presentation format. Think about how you can use these techniques for selling ideas, explaining technical concepts, brainstorming, etc. For more ideas on low-tech requirements gathering, see my previous post as well.
Saturday, July 7, 2007
LiveEarth not in the top 10?!
Whoever organized LiveEarth really missed the blogosphere. A few points of evidence:
1. There are only 2049 blog posts on LiveEarth?
2. LiveEarth as a search term isn't hitting the Technorati top 10.
3. The LiveEarth facebook group only has 678 members.
Whoever is responsible for creating Buzz on the blogsophere for LiveEarth is doing a poor job - Paris Hilton and the IPhone are doing much better than LiveEarth, a supposedly global change event.
I'm going back to enjoying the music on the old fashion technology called the Television! :)
Problems with Live Earth Broadcast
Compared to the Live8 broadcast that AOL did, the LiveEarth broadcast is a disappointment. The resolution of the video is significantly poorer and yet I'm finding that the stream is having a lot of problems handling the load. There are a lot of blackouts, frequent rebuffering of content and there have already been complaints that the site only works in Internet Explorer.
This could have been a fantastic showcase for Silverlight - with the quick download of the plugin Microsoft could have showcased its new technology including some fantastic video streaming.
But instead we see choppy video, disconnected audio and very slow response rate on the interface.
What a missed opportunity!
Friday, July 6, 2007
Creating a Single Sign-On Solution for .NET Part 2
For the past couple days I've been building my single sign-on solution based on my previously posted design.
I built some simple web services that allow for login against a membership profile database using the supplied ASP.NET membership architecture. By registering the membership and logging in, we can provide a token that can be used to represent the logged in user. This token can then be distributed on the URL and passed to partner sites. The partner site can the validate the token and retrieve the membership information through a web service method.
Here is the code:
using System;
using System.Data;
using System.Web;
using System.Web.Caching;
using System.Web.Security;
using System.Collections;
using System.Web.Services;
using System.Web.Services.Protocols;
using System.ComponentModel;
using System.Web.Profile;
using System.Configuration;
using System.Security.Principal;
namespace SingleSignOn.WebService
{
[WebService(Namespace = "http://localhost/")]
[WebServiceBinding(ConformsTo = WsiProfiles.BasicProfile1_1)]
[ToolboxItem(false)]
public class MemberWebService : System.Web.Services.WebService
{
///
/// Logs in a user and provides back a token. Tokens can then be used to regrab the profile data.
///
///
///
///
[WebMethod]
public string registerMember(string userName, string password)
{
if (Membership.ValidateUser(userName, password))
{
Guid token = Guid.NewGuid();
HttpContext.Current.Cache.Insert(token.ToString(), userName, null, Cache.NoAbsoluteExpiration, TimeSpan.FromMinutes(20));
return token.ToString();
}
else
return null;
}
///
/// Validates a token and provides back a membership user in return. If the member isn't found then null is returned.
///
/// Token to validate.
///MembershipUser object for the mapped user. If token isn't found then null is returned.
[WebMethod]
public MembershipUser validateMember(string token)
{
string userName = (string) HttpContext.Current.Cache[token];
MembershipUser member = Membership.GetUser(userName);
return member;
}
///
/// Returns the current profile object.
///
/// Token to map to a currently logged in user.
///Array of name value pairs.
[WebMethod]
public object[][] getProfile(string token)
{
string userName = (string)HttpContext.Current.Cache[token];
Hashtable profileHash = new Hashtable();
ProfileBase profile = WebProfile.Create(userName, true);
foreach (SettingsProperty property in WebProfile.Properties)
{
profileHash.Add(property.Name, profile[property.Name]);
}
return toJaggedArray(profileHash);
}
///
/// This doesn't work. I have not yet found a way to update profiles properly in ASP.NET.
///
///
///
///
[WebMethod]
public void updateProfileProperty(string token, string propertyName, string value)
{
try
{
}
catch (Exception e)
{
System.Diagnostics.Debug.Print(e.Message);
}
}
///
/// Invalidate the cache entry containing the token.
///
/// Token representing user
[WebMethod]
public void logout(string token)
{
HttpContext.Current.Cache.Remove(token);
}
private object[][] toJaggedArray(Hashtable ht)
{
object[][] oo = new object[ht.Count][];
int i = 0;
foreach (object key in ht.Keys)
{
oo[i] = new object[] { key, ht[key] };
i++;
}
return oo;
}
private Hashtable toHashtable(object[][] oo)
{
Hashtable ht = new Hashtable(oo.Length);
foreach (object[] pair in oo)
{
object key = pair[0];
object value = pair[1];
ht[key] = value;
}
return ht;
}
}
}
One small technical note - because web services don't support Hashtables, you need to convert these to a more basic array in order to return them. See the getProfile method as an example.
There is one fundamental problem - trying to manage other people's profiles. It seems that the ASP.NET profile management is based on the assumption that you are reading and writing a current logged in user's profile context. However, in this case, we want to be able to proxy the profile data out to the world which means being able to read and write any user's profile data. There doesn't seem to be an easy way to do this in the current profile architecture. You can get a Profile object from the HttpContext, but this is the current logged in user. You can use the ProfileManager class to grab profile objects but it doesn't provide you access to individual properties of the profile. You can load up a profile object using the GetProfile method, but then there is no way to save the profile.
So it seems that if I'm going to use a distributed global profile management system, I'm going to have to build my own. This isn't really a huge problem as the built in profile management system is fairly weak (see my previous post on general problems with the ASP.NET profile) and building a basic profile management system to store name value pairs or serialized objects isn't that difficult.
But the good news is the basic idea of proxying a token across a domain to store a logged in user seems to work in principle. The next challenge is figuring out the best way to secure it so that only valid partner sites can use the service.
I built some simple web services that allow for login against a membership profile database using the supplied ASP.NET membership architecture. By registering the membership and logging in, we can provide a token that can be used to represent the logged in user. This token can then be distributed on the URL and passed to partner sites. The partner site can the validate the token and retrieve the membership information through a web service method.
Here is the code:
using System;
using System.Data;
using System.Web;
using System.Web.Caching;
using System.Web.Security;
using System.Collections;
using System.Web.Services;
using System.Web.Services.Protocols;
using System.ComponentModel;
using System.Web.Profile;
using System.Configuration;
using System.Security.Principal;
namespace SingleSignOn.WebService
{
[WebService(Namespace = "http://localhost/")]
[WebServiceBinding(ConformsTo = WsiProfiles.BasicProfile1_1)]
[ToolboxItem(false)]
public class MemberWebService : System.Web.Services.WebService
{
///
/// Logs in a user and provides back a token. Tokens can then be used to regrab the profile data.
///
///
///
///
[WebMethod]
public string registerMember(string userName, string password)
{
if (Membership.ValidateUser(userName, password))
{
Guid token = Guid.NewGuid();
HttpContext.Current.Cache.Insert(token.ToString(), userName, null, Cache.NoAbsoluteExpiration, TimeSpan.FromMinutes(20));
return token.ToString();
}
else
return null;
}
///
/// Validates a token and provides back a membership user in return. If the member isn't found then null is returned.
///
/// Token to validate.
///
[WebMethod]
public MembershipUser validateMember(string token)
{
string userName = (string) HttpContext.Current.Cache[token];
MembershipUser member = Membership.GetUser(userName);
return member;
}
///
/// Returns the current profile object.
///
/// Token to map to a currently logged in user.
///
[WebMethod]
public object[][] getProfile(string token)
{
string userName = (string)HttpContext.Current.Cache[token];
Hashtable profileHash = new Hashtable();
ProfileBase profile = WebProfile.Create(userName, true);
foreach (SettingsProperty property in WebProfile.Properties)
{
profileHash.Add(property.Name, profile[property.Name]);
}
return toJaggedArray(profileHash);
}
///
/// This doesn't work. I have not yet found a way to update profiles properly in ASP.NET.
///
///
///
///
[WebMethod]
public void updateProfileProperty(string token, string propertyName, string value)
{
try
{
}
catch (Exception e)
{
System.Diagnostics.Debug.Print(e.Message);
}
}
///
/// Invalidate the cache entry containing the token.
///
/// Token representing user
[WebMethod]
public void logout(string token)
{
HttpContext.Current.Cache.Remove(token);
}
private object[][] toJaggedArray(Hashtable ht)
{
object[][] oo = new object[ht.Count][];
int i = 0;
foreach (object key in ht.Keys)
{
oo[i] = new object[] { key, ht[key] };
i++;
}
return oo;
}
private Hashtable toHashtable(object[][] oo)
{
Hashtable ht = new Hashtable(oo.Length);
foreach (object[] pair in oo)
{
object key = pair[0];
object value = pair[1];
ht[key] = value;
}
return ht;
}
}
}
One small technical note - because web services don't support Hashtables, you need to convert these to a more basic array in order to return them. See the getProfile method as an example.
There is one fundamental problem - trying to manage other people's profiles. It seems that the ASP.NET profile management is based on the assumption that you are reading and writing a current logged in user's profile context. However, in this case, we want to be able to proxy the profile data out to the world which means being able to read and write any user's profile data. There doesn't seem to be an easy way to do this in the current profile architecture. You can get a Profile object from the HttpContext, but this is the current logged in user. You can use the ProfileManager class to grab profile objects but it doesn't provide you access to individual properties of the profile. You can load up a profile object using the GetProfile method, but then there is no way to save the profile.
So it seems that if I'm going to use a distributed global profile management system, I'm going to have to build my own. This isn't really a huge problem as the built in profile management system is fairly weak (see my previous post on general problems with the ASP.NET profile) and building a basic profile management system to store name value pairs or serialized objects isn't that difficult.
But the good news is the basic idea of proxying a token across a domain to store a logged in user seems to work in principle. The next challenge is figuring out the best way to secure it so that only valid partner sites can use the service.
Wednesday, July 4, 2007
Creating a Single Sign-On Solution for .NET
We have a basic single sign-on requirement. We need to be able to allow users to login and pass that login to other distributed systems.
Here are the basic requirements:
1. We want to control the master user profile so that we can have access to the data and integrate it into our offline CRM systems.
2. We have a number of partners who provide hosted applications for us that require authentication. We need to provide a mechanism to have a single sign-on for users that can then be passed to to these partners.
3. The partners may have their own profile requirements that are independent of our needs. For example, let's assume we have a partner that provides community forums and saves the user's favourite forums in their profile. Only the partner cares about this information and centralizing it doesn't add any real value.
4. The solution has to work in a distributed, multi-platform environment. The only access to and from the partners and us is through port 80 using either REST or Web Services calls.
5. The domain may not be the same and therefore you cannot share cookies (see http://www.codeproject.com/aspnet/aspnetsinglesignon.asp and www.411asp.net/func/goto?id=5998410 for a solution based on the assumption that you can simply poke the cookie created by ASP.NET)
6. There needs to be a way to transfer state from one server to another in cases where the user is logged in already. If user logs in Site A and then goes to Site B, they should appear to be still logged in.
So here is the basic design:

1. User logs in by calling a login web service method (see this example for a web services method implementation of login). User is now authenticated on the main site.
2. User links to partner site which passes a token representation of the state (we could use the SessionID itself in .NET as a token).
3. The partner site receives the token and calls a ValidateToken web service method. This validates the passed in token and provides back the membership information for the current user.
4. If the partner site collects user information, the site can call the Update web service method to update the master profile.
5. If the user wants to link back from the partner site to the main site, the partner site provides a link back to the main site with the token embedded in the query string.
6. The main site receives the token and calls a ValidateToken web service method. This validates the passed in token and provides back the membership information for the current user.
This basic architecture should work with a couple basic caveats:
1. State needs to be managed centrally with the usual challenges of managing session state in a load balanced environment.
2. There needs to be some security around the token validation service to prevent malicious sites from getting access to the service. There are lots of solutions for this including putting the web services under VPN, including a site authentication mechanism in the web service method, filtering by IP, etc.
3. Each link needs to be dynamically re-written to include the token. If there are lots of existing cross-over points then this could be a challenge.
4. The parsing of the token needs to happen on every page request. In .NET this could be done using an HTTP Module as a central parsing code. Alternatively, you could have a redirect page that all pages link to first with the original target url embedded in a query parameter (this is how typical login pages work for example).
5. There needs to be some mechanism for keeping the state alive so that it doesn't time out. This could again done using an HTTP Module that on every page request does a web service request to validate token to simply keep the state alive.
6. The solution assumes that there is a single backing master profile that distributes profile information. A "peer to peer" type model could be developed but it would be more complicated.
From a look and feel perspective, the solution doesn't require a single login or registration experience but it probably would make sense. Keep the login and registration forms on the main web site and have them redirect back to the partner site if the request is coming from the partner.
Implementing an Agile Change Control Process
What is Change Control?
Change Control traditionally is a project management process for managing change. The typical method for managing change in a classic PMP project is a Change Control form that is filled out containing the scope of the change, impact to the project, etc. This is then approved and incorporated into the master project plan, charter, etc.

In addition, Change Control processes are used by operations departments to manage the deployment and promotion of code from one environment to another. The Change Control Form provides the documentation for an operations team to deploy, operate and monitor the change.
Change Control and Agile
This traditional view of Change Control is at odds with Agile methodologies for the following reasons:
1. Change is viewed as a non-typical event, e.g. the project was running smoothly until someone threw a change into the project. Agile projects by definition are based on the assumption that changes are typical events and aren't special.
2. Change requests are simply Waterfall designs in miniature. Requirements for the change must be documented up front and analyzed. Stakeholders must approve of changes before they are made with the assumption that requirements, scope, risk, and design can be formally documented ahead of making a code change.
3. Traditional Change Control processes are document heavy. The process is designed as much to capture and document change as it is to make effective decisions. Change control forms are kept around forever with dates and identifiers so that someone could find out who approved a change. In many cases, these are also printed out, resulting in very large binders of paper with signatures for every change.
4. In an agile project, one of the objectives is to flatten the team and reduce hierarchies so that people can more effectively communicate. However, traditional change control processes require specialized knowledge, special powers of approval and a hierarchical command and control structure. Project Managers are usually the writers of change control forms, but then they must get approval from "Stakeholders" who will bless the change.
Here is a good example of a traditional Change Control process - have a look at Bell South's Change Control Process Guide. At 120 pages, it is a great example of how bloated a large formal change control process can get when Project Managers are working in a bureaucratic environment. Just managing the process documentation alone takes a massive investment - just look at the 20 pages of version numbers of this document and you'll see that someone's full-time job must be simply keeping the guide up to date!
Change Control isn't a bad thing - the original objectives behind formal Change Control are actually in line with the objectives of agile methodologies:
1. Define change and anticipate change early instead of leaving it to the end.
2. Providing a process for incorporating change during development of a project.
3. Communicate scope, risks and impacts of a change.
4. Provide the appropriate review and approval process to authorize a change.
It isn't that change control is bad - it's that the evolution of formal project methodologies has led to very bureaucratic, documentation heavy processes. In addition, keep in mind that most of these processes were invented before the incorporation of digital collaboration tools such as email, Wikis, sharepoint, JIRA, Word, etc. and so the typical change control process has artifacts from a non-digital era.
Implementing an Agile Change Control Process
Change Control can be used effectively in an Agile environment if it is sufficiently light weight, non-bureaucratic and collaborative. Here are my recommendations based on what I have seen work effectively on Agile and non-Agile projects:
1. Use an agile methodology such as XP, Crystal, Scrum, etc. that has change management built into its fundamental process. In Scrum, for example, all work is effectively a change and is logged as a "change request" in a work backlog. In XP the changes are logged as User Stories. Iterations allow for changes to happen on a regular basis - they're not special change events.
2. Use a generic task tracking system such as JIRA to log any change. In JIRA, you don't need a separate "bug tracking" system that is different than your change tracking system. In addition, you can take a change all the way from requirements to deployment without re-entering information. You could do the same thing with low tech tools such as Excel or Word simply by having a work log that is updated regularly.
3. If you have specific legal or regulatory reasons to track changes then try to understand the specific minimum requirements. I've worked in a government environment for example where all changes needed to be documented so that they could be audited. But the level of detail that was incorporated into each Change Control form became ridiculous - an auditor probably doesn't really need to see a change in an individual SQL script, a deployment checklist that includes changing ODBC connection strings, etc.!
4. Eliminate as many approvals as possible. We had a change control form that had 10 signatures on it - I was one of them! I used to get these forms across my desk documenting some change to an application that I had never even seen, had no idea how to measure the risk of the change and yet I was expected to "approve" it. Even worse, the signature had to be on paper so there was a constant stream of people running around with pieces of paper trying to find me to get my signature. Eliminate all this process and identify the minimum number of people who need to be involved in any change.
5. If you're going to have a Change Control Form/Process, keep in as light as possible. Your form should be no more than 2 pages and should be as automated as possible. We currently use JIRA to automate all our tickets. In previous environments, we've used Outlook forms. I've also seen this done use Word with Macros enabled to provide drop downs, automatic fill-in, etc. Keep your process light as well - if you need 2 hours of training to teach someone how to make a code change, then something is wrong!
6. Keep Operations teams involved from day one. One of the primary reasons why change control forms are deployed is because Operations teams get tired of having code dumped on them without documentation or involvement. The typical solution is to put in a gate keeping process to keep the developers from deploying something unsafe to production. This is a legitimate role, but change control processes typically provide artificial security - simply because a developer has filled in the proper form doesn't mean their code works as advertised. Instead, have an Operations Lead that is an integral part of the project from day one who will have a specific understanding of the project and create the right level of documentation, deployment guides, test cases, etc. and be testing these along the way. This is far more effective than a large form being written at the end of the cycle.
7. Keep stakeholders involved throughout the project. The reason why Change Control forms need to be so heavily documented is because the key stakeholders have not been involved all along the way. If stakeholders are seeing working software using Show and Tell techniques, then Change Control simply becomes regular involvement in the project.
8. Use multiple models of communication. Instead of having a single Change Control Form that forces people to write in a specific way, allow for multiple models of communication that could include meetings, power point presentations, white boards, Visio diagrams, etc.
Based on the above principles, here is my current favorite flavour of Change Control:
1. We build our requirements using use case documents that living documents. We currently use Word because its dumb simple and stakeholders can easily open it and change it. We use power point for wire frames and Visio for almost everything else.
2. Revisions of documents get stored in source code control for safe keeping and history. However, we're not dogmatic about it and in my experience the value of these minor revisions is usually not significant - most stakeholders want to see the current version. We keep them in our repository so that everything is stored together and document revisions are tied to code revisions.
3. We have iterations every 2 weeks that include review meetings with the entire team including stakeholders. We do a show and tell of all working code and we use the meeting to prioritize and change. We typically do this by opening up documents on the spot, but sometimes we use pen and paper and transcribe the changes right after the meeting.
4. We use JIRA for day to day tracking of tasks. We treat all changes, bugs, feature requests and tickets the same way. We have a very simple work flow that moves all tasks from open to resolved to closed. Our list of changes can be pulled directly from JIRA as a list of changes. The list of outstanding bugs can be also pulled at any time so we don't need a specific final bug review meeting - we will have been reviewing them on a daily basis.
5. When we're getting close to deployment, we use white board based checklists to capture the minute details (e.g. make sure the ODBC driver is configured properly) that need to be done to move to production. We check these off by simply crossing them off or wiping them from the list. We have 15-20 minute stand-up meetings that includes the Operations Lead so that we're communicating effectively with Operations and they know exactly where things are at as we move into production.
6. Just before doing a deployment to production, I have a meeting with executive stakeholders with a very high level presentation in power point. It presents the current status, any risks that they need to understand, confidence in going, and high level operations plan. Executives typically don't care about whether the SQL is right - they want to know that the team has confidence that it can deploy safely, has followed the appropriate testing processes and that the team is on standby with a contingency plan in case things go wrong.
There are lots of variations to this process and many different tool combinations. You can scale the process up or down depending on the size and formality of the project. In addition, if you're working in a specific regulatory context you may need to be producing more formal documents, approvals, audit trails, etc. My suggestion is always prioritize these below communication and if you need to do this for regulatory purposes then do so but keep the work as minimized as possible. Never substitute change control processes for good communication, team collaboration, stakeholder involvement, etc. In addition, remember that Change Control is a means and not an end - working software is the objective and should be focus for the team.
Sunday, June 24, 2007
Communication of Software Risks
One of the interesting challenges in managing a project is estimating technical risk.
Here is an example of a classic technology risk scenario:
The development team is building an online transaction system that sends orders from an e-commerce system to a warehouse. The e-commerce system is internal, the warehouse is external. The warehouse works on an AS400 system and no one on the team has ever worked with AS400 platforms before. There is a defined web services layer between the two systems which should hopefully hide the workings of the AS400 system behind the layer.
This is a pretty typical high level description of requirements from a manager, a request for proposal, or an email.
Most developers look at this and start analyzing all the things that could go wrong...there are dozens of risks just in this one paragraph.
A project manager might realize that there are some risks involved and if the PM has a technical background might be starting to ask some risk based questions that show some understanding of the potential problems. The worst case scenario is a non-technical PM who thinks that this project is the equivalent of ordering pizza from Domino's - you simply call and expect the order delivered by the guaranteed delivery window.
Let's assume that the entire team is on the ball, everyone's working together and the team comes together to review the project plan. A risk matrix gets created and the team comes up with the following risks:
Risk: Web Service might not work
Probability: Medium
Impact: High
Risk: AS400 might have performance problems
Probability: Medium
Impact: Medium
Risk: Transactions might not work across the two distributed systems.
Probably: High
Impact: Low/Medium
and so on....
This is the critical point where there is a massive communication gap between what a typical PM thinks a risk impact is and what a developer think of a risk impact.
A PM may think, "Well we have some risks so we should allocated some contingency in the budget. This is a high risk project, so we'll add in 30% contingency to our estimate and a month onto the time line."
A Developer may think: "If this server cannot move data fast enough, we're dead in the water. It won't matter how much time or money you throw at it because short of hauling out the entire AS400 out the warehouse we're toast."
Big difference in risk!
I've seen projects where there were mature team members and did all the traditional risk analysis that is recommended on software projects. But the project still failed because there were fundamental differences in assumptions in what "High Risk" actually meant to cost, time line and project success.
Here are some common reasons why there are differences in assumptions around risks.
1. Team members don't all have the same assumptions on impact of a risk. For example, a task is estimated at 3 days but the impact of the risk is "High". So what does that mean to the estimate? Add 10%? Add 50%? What about 10X? In my experience, project managers in particular do not understand the sheer magnitude of software risks - they'll see a risk as "High" and put in contingency of an additional 30% and think they're good to go.
A 10X risk impact is not unheard of - I've seen it myself on many projects. We had one project where one web service call was supposed to take 3 days and took 30 days because of technical complications.
2. There are some risks that result in project failure because in some cases requirements are not variable. For example, financial data cannot be more or less correct - its either right or its wrong. So getting to 80% right isn't really valuable - if you cannot hit the 100% mark then your software project fails. So if you have a risk that the data isn't going to be right then it isn't so much that your project went over budget or took too long to deliver - its a total failure because it cannot meet the basic requirements. Same thing with external software dependencies - for example we had a case where we were integrating with a web services framework and there was a bug in one of the supplied web services from the vendor. It wasn't a matter of "let's just find a work around" - the project was effectively dead in the water until that bug was solved.
Project managers tend to be solution oriented and optimistic, so while they like the idea of contingency, they tend to shy away from the concept that a risk might actually kill their project with no way to get around it.
3. The "I don't know" estimate will get quantified too early on in the process or not be listened to at all. If your team is saying, "I don't know" as a project manager, what is your approach? Many PMs are forced into providing estimates too early by management, so they simply fudge the "I don't know" into a contingency or pad the estimate. They think that by taking the developer's estimate and doubling it they've been given themselves a massive breathing space to worry about the problem later.
The cone of uncertainty on typical projects is a lot bigger than most PMs realize - Steve McConnell's work on estimation pegs the variance at 1600%!

If the team doesn't have a common understanding of how to quantify the impact of risks, then everyone can be communicating using a traditional risk process but the shared understanding of the impact of any risk will tend to be different.
Here are some recommendations for Project Managers for creating an improved risk communication culture:
1. Vary the risk based on expected uncertainty level and the phase of the project. For example, if you're in the planning phase the expected uncertainty level is high. If someone on the team says, "Well we don't really know how that's going to work but we have a plan" that's probably OK. If you hear the same thing in the middle of QA, then you should be very concerned and adjust accordingly.
2. Have the team translated risks from labels ("High", "Medium", "Low") to numbers where possible. In addition, don't assume that one set of labels means the same across the project. For example, a "High Risk" HTML issue might be something very different than a "High Risk" web services integration issue or performance issue.
3. Identify the requirements that are absolute and unmovable and pay particular attention to risks that are around them. For example, in some cases performance is an absolute requirement (e.g. it must serve 30 pages per second) and sometimes it isn't (it must be "fast"). If your requirements are absolute then any risk that hits those requirements will not just cause a delay, an increase in cost, etc. - it will kill your project.
4. Pay close attention to areas of the project where there is limited flexibility or options. Compare the flexibility of a creative front end vs. a bought software system. If someone doesn't like the the front-end, you can rebuild it, change it, etc. It might cost more, create a time impact, etc. but you've got lots of flexibility for change. If you buy Microsoft Content Management Server and it has a bug in it your options are pretty limited.
5. "I don't know" must be a viable option in any discussion. In addition, the response to "I don't know" should be to go find out - be careful about arbitrary padding of estimates simply to factor it into your plan.
6. Pay close attention to body language, talent and historical experience. Relationships matter in software teams and a team that has worked together before has the advantage that the PM starts to recognize the subtleties of individual communication styles and to understand how each person reacts to different questions or risks. Is John an optimist or a pessimist? When someone says, "I don't know" are they being cagey or honest? Teams who have worked together start to intuitive find out these non-verbal cues.
7. Review risks on a regular basis so that you can refine your strategies to mitigate them.
Hopefully that helps you in creating a more pro-active risk based approach and to be aware that just because people the team are calling somet "high risk" they may not actually mean the same thing.
Here is an example of a classic technology risk scenario:
The development team is building an online transaction system that sends orders from an e-commerce system to a warehouse. The e-commerce system is internal, the warehouse is external. The warehouse works on an AS400 system and no one on the team has ever worked with AS400 platforms before. There is a defined web services layer between the two systems which should hopefully hide the workings of the AS400 system behind the layer.
This is a pretty typical high level description of requirements from a manager, a request for proposal, or an email.
Most developers look at this and start analyzing all the things that could go wrong...there are dozens of risks just in this one paragraph.
A project manager might realize that there are some risks involved and if the PM has a technical background might be starting to ask some risk based questions that show some understanding of the potential problems. The worst case scenario is a non-technical PM who thinks that this project is the equivalent of ordering pizza from Domino's - you simply call and expect the order delivered by the guaranteed delivery window.
Let's assume that the entire team is on the ball, everyone's working together and the team comes together to review the project plan. A risk matrix gets created and the team comes up with the following risks:
Risk: Web Service might not work
Probability: Medium
Impact: High
Risk: AS400 might have performance problems
Probability: Medium
Impact: Medium
Risk: Transactions might not work across the two distributed systems.
Probably: High
Impact: Low/Medium
and so on....
This is the critical point where there is a massive communication gap between what a typical PM thinks a risk impact is and what a developer think of a risk impact.
A PM may think, "Well we have some risks so we should allocated some contingency in the budget. This is a high risk project, so we'll add in 30% contingency to our estimate and a month onto the time line."
A Developer may think: "If this server cannot move data fast enough, we're dead in the water. It won't matter how much time or money you throw at it because short of hauling out the entire AS400 out the warehouse we're toast."
Big difference in risk!
I've seen projects where there were mature team members and did all the traditional risk analysis that is recommended on software projects. But the project still failed because there were fundamental differences in assumptions in what "High Risk" actually meant to cost, time line and project success.
Here are some common reasons why there are differences in assumptions around risks.
1. Team members don't all have the same assumptions on impact of a risk. For example, a task is estimated at 3 days but the impact of the risk is "High". So what does that mean to the estimate? Add 10%? Add 50%? What about 10X? In my experience, project managers in particular do not understand the sheer magnitude of software risks - they'll see a risk as "High" and put in contingency of an additional 30% and think they're good to go.
A 10X risk impact is not unheard of - I've seen it myself on many projects. We had one project where one web service call was supposed to take 3 days and took 30 days because of technical complications.
2. There are some risks that result in project failure because in some cases requirements are not variable. For example, financial data cannot be more or less correct - its either right or its wrong. So getting to 80% right isn't really valuable - if you cannot hit the 100% mark then your software project fails. So if you have a risk that the data isn't going to be right then it isn't so much that your project went over budget or took too long to deliver - its a total failure because it cannot meet the basic requirements. Same thing with external software dependencies - for example we had a case where we were integrating with a web services framework and there was a bug in one of the supplied web services from the vendor. It wasn't a matter of "let's just find a work around" - the project was effectively dead in the water until that bug was solved.
Project managers tend to be solution oriented and optimistic, so while they like the idea of contingency, they tend to shy away from the concept that a risk might actually kill their project with no way to get around it.
3. The "I don't know" estimate will get quantified too early on in the process or not be listened to at all. If your team is saying, "I don't know" as a project manager, what is your approach? Many PMs are forced into providing estimates too early by management, so they simply fudge the "I don't know" into a contingency or pad the estimate. They think that by taking the developer's estimate and doubling it they've been given themselves a massive breathing space to worry about the problem later.
The cone of uncertainty on typical projects is a lot bigger than most PMs realize - Steve McConnell's work on estimation pegs the variance at 1600%!
If the team doesn't have a common understanding of how to quantify the impact of risks, then everyone can be communicating using a traditional risk process but the shared understanding of the impact of any risk will tend to be different.
Here are some recommendations for Project Managers for creating an improved risk communication culture:
1. Vary the risk based on expected uncertainty level and the phase of the project. For example, if you're in the planning phase the expected uncertainty level is high. If someone on the team says, "Well we don't really know how that's going to work but we have a plan" that's probably OK. If you hear the same thing in the middle of QA, then you should be very concerned and adjust accordingly.
2. Have the team translated risks from labels ("High", "Medium", "Low") to numbers where possible. In addition, don't assume that one set of labels means the same across the project. For example, a "High Risk" HTML issue might be something very different than a "High Risk" web services integration issue or performance issue.
3. Identify the requirements that are absolute and unmovable and pay particular attention to risks that are around them. For example, in some cases performance is an absolute requirement (e.g. it must serve 30 pages per second) and sometimes it isn't (it must be "fast"). If your requirements are absolute then any risk that hits those requirements will not just cause a delay, an increase in cost, etc. - it will kill your project.
4. Pay close attention to areas of the project where there is limited flexibility or options. Compare the flexibility of a creative front end vs. a bought software system. If someone doesn't like the the front-end, you can rebuild it, change it, etc. It might cost more, create a time impact, etc. but you've got lots of flexibility for change. If you buy Microsoft Content Management Server and it has a bug in it your options are pretty limited.
5. "I don't know" must be a viable option in any discussion. In addition, the response to "I don't know" should be to go find out - be careful about arbitrary padding of estimates simply to factor it into your plan.
6. Pay close attention to body language, talent and historical experience. Relationships matter in software teams and a team that has worked together before has the advantage that the PM starts to recognize the subtleties of individual communication styles and to understand how each person reacts to different questions or risks. Is John an optimist or a pessimist? When someone says, "I don't know" are they being cagey or honest? Teams who have worked together start to intuitive find out these non-verbal cues.
7. Review risks on a regular basis so that you can refine your strategies to mitigate them.
Hopefully that helps you in creating a more pro-active risk based approach and to be aware that just because people the team are calling somet "high risk" they may not actually mean the same thing.
Thursday, June 21, 2007
Developer Weasel Words
As a development manager or project manager, you here a lot of weasel words and excuses from your staff or from external consultants who are trying to hose you into believing things are better than they are. In many cases, developers use these phrases to even convince themselves that things are better than they are, resulting in chronic late delivery and poor quality.
So beware the following phrases from your teams:
So beware the following phrases from your teams:
- It should work: this usually means that it doesn't. It also means that it was probably not tested properly as the result is current undetermined. The word "should" should be taken out every developer's vocabulary - it either does or it doesn't.
- I just need: beware of that word "just". Its a belittling word meant to make things smaller than they are. Just take the phrase "I just need to write this component" to be "I need to write this component" and already the magnitude of the work involved grows. Developers tend to be chronic under-estimators and the use of the word "just" is a sign of that mentality.
- Almost done: this is also a weasel word. When a developer tells you things are "almost done" ask for the specific tasks that are left over immediately. In addition, keep in mind that projects do not progress linearly - the last 10% is always about 40-50% of the work of the total project. I've seen projects that are chronically late be "almost done" for 3 months.
- It was tested: this also usually means it that wasn't tested properly. Ask for a test plan and the specific tests that were done. If the developer cannot produce these with sufficient evidence that PROVES that it was tested, then it wasn't tested.
- It must be an environment/configuration/deployment problem: this may be actually true, but it usually points to a larger stability problem. If you cannot build and deploy reliably then why would you have confidence that the code works?
- If things go smoothly: this I hear a lot, e.g. if we don't hit any snags then we can be done by Friday. Guess what - you're likelihood of hitting a "snag" by next Friday is probably high and given the lack of risk based management, the team has probably got no mitigation or contingency strategy. Then next week, you'll hear the next phrase in our list, "Yes, it could have been done if it weren't for that Snag we had".
- Yes, but, as in "Yes it can be done, but": this means it cannot be done. Tell your staff to just come clean and say, "No it cannot be done". Another variant on this is, "Yes it could have been done, if it weren't for marketing, requirements, technical risk, etc." This simply shows that your developers work in an idealistic world where things never go wrong.
- We'll make up the time at the end: if you're already late by the end of requirements, you're likely going to be even later by the end if you simply keep going on the same track. In my experience, teams don't dramatically faster as they hit their stride. Even if there is some efficiency, its nowhere enough to make up for lost time.
- I've got it done, but I need to build a few more components for you to be able to see it: then its not done! Encourage show and tells, code reviews, unit tests, etc. so that code is visible as soon as possible. Use slicing models so that you can see pieces of the application in weeks, not months. In addition, code that isn't checked in should never be counted - that means that someone cannot build it sufficiently to share it. It only counts if you can verify it. Ideally, its not "done" unless there are sufficient unit tests, a build script, and a document that someone walking into the code repository could check out the project run a build and have all the unit tests pass. Then the code is done - anything less is mythical.
- I've got it done - I just need to integrate it: The word "Integrate" is a big weasel word. Think of a web service that adds two numbers together. The algorithm is one line of code. But the integration work is huge. In addition, integration usually means the first time that disparate teams are bringing code together which is always cause for issues. Don't under-estimate the integration, especially in today's world of distributing computing, web services, etc.
- It Worked on my Machine!: programmers use this excuse to downplay a bug. The reality is actually the opposite - it means that you have an intermittent bug which is by far the worst kind of bug to have in your application. You want bugs to fail quickly and consistently - any variant such as "That's Weird", "That didn't happen yesterday", "That must be a data problem", etc. is admitting you have a bug that cannot be easily duplicated.
My recommendations to reduce the amount of excuse making from your team:
- Encourage a culture of honesty and team work: You get these excuses when developers are hiding things, and sometimes this is because you've created a culture that encourages hiding because you don't want an honest answer.
- Be ruthless with your quality and talent standards: don't excuse poor talent, bad management or chronic late delivery. If you create a culture where talent isn't rewarded the bar isn't kept high then you'll be excusing the team to continually strive for excellence.
- Expect more than just code: measure performance based on estimation, quality, delivery and team work as well as pure code quality. If you have a developer who produces great code but cannot deliver on time then that's not a great developer.
- Increase visibility and shrink delivery cycles: if you have to show your work on a constant basis and deliver on 2 week iteration cycles, your excuses tend to go away. You either deliver or you get found out pretty quickly. Use show and tells, code reviews and continuous integration to see what people are doing on a constant basis.
- Don't give half credit for 50% done - its either done or not done: If your tasks cannot be managed this way, then you should split up your tasks until you can work this way.
- Establish what "Done" really means: for example, at a minimum "Done" should mean checked into source code control and able to build into the current branch. If you're doing Test Driven Development, it should also mean all tests run successfully. If you have specific performance criteria, then its not "Done" until the performance tests pass.
- Use counting techniques to measure wherever possible: this is a great suggestion from McConnell's book on estimation. The more you can count in units, the more accurate you estimation. So if you can count the number of pages, web services, objects, databases, tables, stored procedures, tasks, etc. that are left to accomplish then you can measure them more easily than if its a big blob of work. If your requirements aren't well defined enough to count objects, e.g. you don't know how many web pages you're building in your web site, then you're really not in a position to estimate your ship date.
- Don't sucker, manipulate or bully your team: If as a project manager, you resort to traditional management tactics such as playing games, being political, establishing a blame culture, or bullying your team you'll lose your credibility and simply encourage lying. A tortured prisoner will tell you anything you want to hear - the same goes with development teams.
If you have a project that operates in the open, has a culture of honesty and establishes a high performance bar, you'll find that peer pressure as well as some overall guidance will get risks, problems and bugs out in the open. If when you discover these problems people work as a team to fix them instead of blaming each other then every problem solved becomes a victory and not a blame opportunity. You'll get better answers and improved morale on the team as you set clearer performance expectations.